AI Context: Tutorial & Examples
Reviewed by Patronus AI team
Large language models (LLMs) use two types of content to generate outputs. The first is the content the model was trained on, which gets encoded into the model’s parameters and is called its parametric knowledge. The second is everything else that the LLM is given or that it retrieves before it produces an output, which is called context. This includes the system prompt that provides information about the LLM’s role and constraints, the user’s prompt and message history, content retrieved from databases and document stores, and more.
In this article, we provide an overview of the different types of information that can be included in an LLM’s context, how you can use context to improve your AI system’s performance, how to optimize your use of context, and some pitfalls to avoid.
Summary of key AI context concepts
The difference between context and knowledge
When a large language model is trained, it learns statistical patterns about how language works and what words are most typically seen together. The model compresses information about vast amounts of text—typically trillions of tokens—into billions of parameters. This is a “lossy compression” that captures general patterns but does not store all of the training data verbatim. What the LLM learns through this training process is called its parametric knowledge.
Note that what the LLM “knows” is not specifically facts about grammar or the world but statistics about a huge corpus of text. It knows how to predict the next token given previous tokens. That said, a trained LLM will typically display emergent capabilities that is often called “implicit knowledge,” including elements like grammatical structures and syntax, semantic relationships and concepts, commonsense knowledge about the world, and imperfect factual information.
There are two ways to customize the behavior of an LLM to a particular task. The first is post-training via techniques such as supervised fine-tuning, reinforcement learning, or direct preference optimization. In these cases, the parameters of the model are modified, changing its parametric knowledge. This is often done to adapt a model’s base capabilities, style, domain expertise, safety behavior, etc.
Alternatively, you can add context to help the LLM complete the tasks you want it to complete. Context starts with the system prompt (e.g., “You are a helpful assistant…”) and includes the user prompt and message history. In a retrieval-augmented generation (RAG) system, context includes a corpus of documents that the LLM can answer questions about. In an agentic system, context includes information about a set of tools available to the agent and the tool-use history. Some LLM-based AI systems also include mechanisms for storing information for future use, such as learned user preferences, information about past projects, or information the AI has chosen or been explicitly instructed to remember.
The amount of context you can provide to an LLM is limited by its context window, that is, the maximum number of tokens that the LLM can process at once to generate a response. For this reason, it is typical to store information (e.g., RAG corpuses, databases for tool access, and memory systems) outside of the current context and give the LLM a means to retrieve (hopefully) just the right pieces of information needed to complete its task.
{{banner-large-dark-2="/banners"}}
Types of AI context
System prompt
The system prompt is the text you set once for your system when setting up API access to an LLM. It sets the basic context for interactions with the user, including the user's role and constraints. (Note that if you are using the chat interface to a cloud-hosted LLM, you likely won’t be able to control the system prompt.)
Role information is often similar to a statement like “You are a helpful customer service assistant.” Constraints may include requirements such as “Prioritize factual accuracy above all else” or “Avoid digressions.” The system prompt is also one place where guardrails can be added, specifying the expected tone or output format or forbidding discussion of certain topics or sensitive information.
User prompt
The user prompt is the specific input that the user provides to specify the task to be completed. A clever user may employ prompt engineering to gain more control over getting the output they want. Users can even train the model to do tasks the way they want them done using few-shot prompting and can often induce better problem-solving behavior by modeling reasoning via chain-of-thought prompting.
Message history
Multi-turn conversations with most LLM chatbots accumulate context in the form of the message history, which includes both the user’s prompts and the system’s replies. When using API access, you will usually need to explicitly manage the message history, accumulating it and passing it back in with each subsequent call. Here’s a simple LangChain code pattern you can use to do this (shown here with OpenAI):
from langchain_openai import ChatOpenAI
from langchain_core.prompts import ChatPromptTemplate, MessagesPlaceholder
from langchain_community.chat_message_histories import ChatMessageHistory
from langchain_core.messages import HumanMessage, AIMessage, SystemMessage
from google.colab import userdata

OPENAI_API_KEY = userdata.get('OPENAI_API_KEY')

# Initialize the ChatOpenAI model
llm = llm = ChatOpenAI(
    model="gpt-4o-mini",
    api_key=OPENAI_API_KEY,
    temperature=0
)

# Create an in-memory chat message history instance
message_history = ChatMessageHistory()

# Add a system prompt
message_history.add_message(SystemMessage(content="You are a helpful assistant."))

# Define a function to handle the conversation and manage history
def converse(user_input: str):

    # Prepare the full list of messages for the *current* model call
    messages_to_send = message_history.messages + [("human", user_input)]
    response_ai_msg = llm.invoke(messages_to_send)
    response_content = response_ai_msg.content

    # Save the user input and AI response to the history for *future* turns
    message_history.add_user_message(user_input)
    message_history.add_ai_message(response_content)

    return response_content
Retrieved document chunks
A typical enterprise use of LLMs is a customer service chatbot. For this and other applications where the AI needs to answer questions based on a given corpus of documents—such as FAQs, product manuals, troubleshooting guides, etc.—RAG provides a way for the LLM to use chunks retrieved from the document corpus as context for the response rather than using its parametric knowledge.
RAG uses a two-step process. An information-retrieval step first retrieves relevant chunks of text from a provided knowledge base (corpus of documents) based on semantic similarity to the query. A generation step then involves generating a response to the query based on the retrieved chunks. Those retrieved chunks are an essential part of the LLM’s context in this paradigm.
Relevant memory
Memory systems allow LLMs to store and retrieve information across sessions. Unlike message history, which maintains the complete conversation within the context window, memory systems selectively store key information—such as user preferences, prior decisions, or content the user explicitly asks it to remember—in external storage. When needed, the system retrieves relevant memories and injects them into the current context. Tools like Mem0 and Zep provide memory management capabilities, deciding what to store and when to retrieve it.
Available tool information
Agentic AI systems extend LLM capabilities by providing access to external tools: functions the agent can invoke to gather information or perform actions. Tools may include things like database queries, web searches, file system operations, or specialized computations. Each tool has a defined interface that specifies its name, required parameters, expected return format, and purpose. The LLM receives these tool specifications as part of its context, enabling it to reason about which tools to use and how to call them.
Tool use history
In multi-step agentic workflows, the accumulated history of tool calls and their results is used as context for completing tasks. This allows the agent to use the results of one tool call to decide what to call next and, ultimately, to synthesize all the results into a final answer for the user.
Types of context retrieval failures
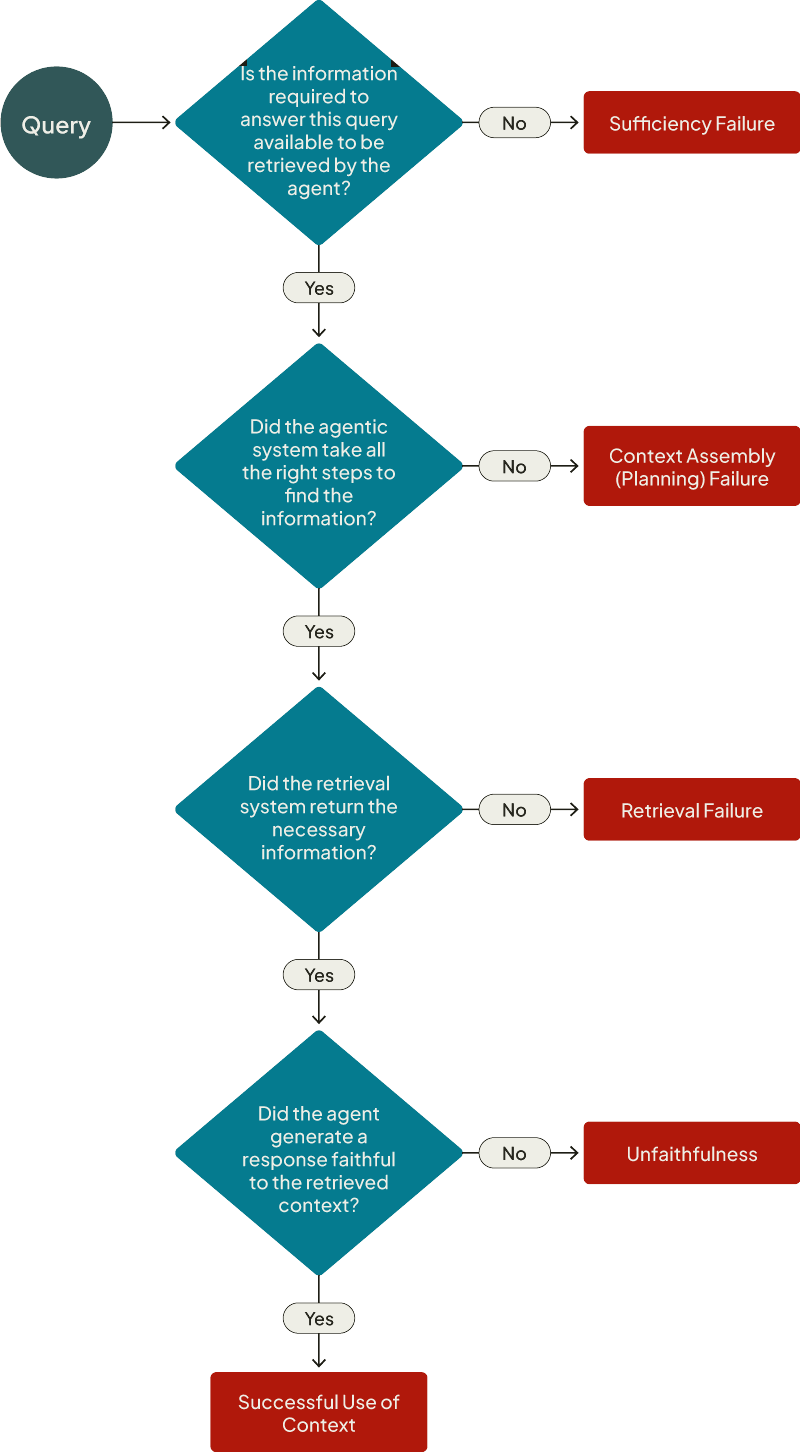
When an AI system needs to retrieve additional context from a RAG corpus, memory, or tool results, there are four main ways this can fail.
Retrieval failures
Retrieval failures occur when a system fails to retrieve the necessary information to answer a query even though the information is available. In RAG systems, this means retrieving incorrect or irrelevant document chunks, either due to poor query formulation or poor information retrieval methods. Memory systems may likewise retrieve irrelevant information, while agentic systems may misuse tools (for example, with incorrect parameter values), thereby preventing them from accessing necessary context.
Sufficiency failures
Sufficiency failures occur when the information needed to respond to the user’s request is not available, which can lead to hallucinated responses. One approach to addressing this is to add an input filter to catch out-of-scope user requests and inform the user that the request cannot be answered. Another way is to use a system prompt that tells the AI to say it doesn’t know rather than hallucinating a response.
Context assembly (planning) failures
Context assembly (or planning) failures occur when an agent fails to take the necessary steps to gather the information needed to answer a query when the means to assemble that information are available to it. The agent might fail to invoke the appropriate tools, gather information in suboptimal order, or stop gathering context prematurely.
Unfaithfulness
Finally, even when the AI system retrieves all the correct context, it may generate a response that is not faithful to it; that is, the generated response is not consistent with or supported by the retrieved content. The model might ignore retrieved documents in favor of its parametric knowledge or synthesize information in ways that contradict the source material.
More context isn’t necessarily better
It’s easy to fall into the trap of thinking that if some context is good, then more is better, and major commercial models now support contexts of hundreds of thousands of tokens. However, it pays to be cautious with using that much context. When you give the LLM too much context, your signal-to-noise ratio plummets, and the model spends tokens (and your time and money) processing irrelevant context rather than reasoning.
When there is too much context, you risk failures:
- Context clash occurs when the LLM’s context contains conflicting information without sufficient instruction as to how to deconflict it.
- Context distraction occurs when an LLM becomes overly focused on the context, and becomes fixated on repeating past actions from its context history.*
- Context confusion occurs when the LLM uses less-relevant content from its context, often calling the wrong tools out of a too-long list, resulting in a low-quality result.
* For more details on context distraction, see the Long Context Reasoning section of the Gemini 2.5 technical report.
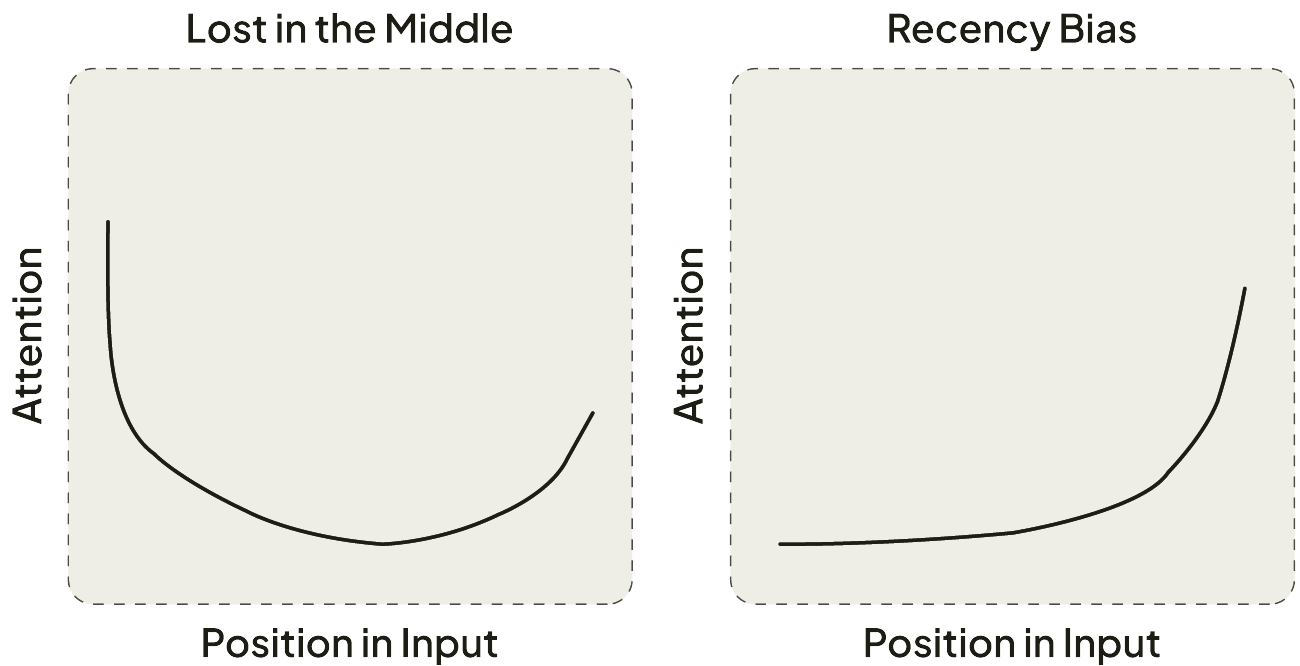
Research has shown that LLMs exhibit positional bias, with their performance depending strongly on where information appears in the context window. The lost-in-the-middle phenomenon (or attention basin) is one of the most consistent ways that position has been shown to matter: When an LLM’s context contains a sequence of structured items (e.g., few-shot examples or RAG document chunks), it tends to assign higher importance to the items near the start and end of the sequence and less to those in the middle. In the case of less structured input, such as long articles or chat transcripts, there tends to be recency bias, where the most recent tokens are given more attention.
Context engineering: designing for context quality and usefulness
Using context effectively can greatly improve the quality of your AI system, so treat it as a first-class concern from day zero, not an afterthought. Ask yourself: “What information does the model need to do its job well?”
Optimize context size and ordering
Keep your context to the minimum necessary size by summarizing when possible and deduplicating aggressively. Be conservative with the number of retrieved results you use: In LLM context retrieval, precision typically matters more than recall because irrelevant or loosely related information consumes scarce context budget, triggers positional-bias failures, and can mislead the model. Remember that missing information generally degrades performance more gracefully than distracting or contradictory context.
Be aware of positional biases. Put the most important instructions and key facts near the end to take advantage of recency bias, and consider using tools like Attention-Driven Reranking (AttnRank) for lists of structured information to reduce the impact of the lost-in-the-middle phenomenon.
Implement context validation
Whenever you add new content to your system’s context, evaluate it to ensure that it is complete, clear, consistent, and effective. Before deployment, check that your instructions are unambiguous and that there are no conflicts between different parts of the context (such as system prompts, tool descriptions, and RAG content). At runtime, automatically check for things like hallucinated IDs, missing fields, retrieval quality, temporal relevance, and contradictions.
Make context observable
Context should be traceable end to end in your application. Log the context provided for each request, tracking retrieved document chunks, tool calls, and results, memory retrieved, etc. See the example below, where a judge LLM reviews an agent’s trace for context errors.
Test boundary cases
Ensure that your system is prepared to deal with situations like:
- Out-of-scope queries
- Retrieval failures
- Tool return errors
- Contradictory context
- Conflicting instructions
- Follow-up queries requiring multi-turn context
Use external memory efficiently
Using external memory can improve your context efficiency; however, a recent study shows that many state-of-the-art AI agents struggle with redundantly reaccessing the same information, and they perform poorly on follow-up questions requiring memory. Using a benchmark like MEMTRACK can help you improve memory efficiency by exposing patterns like redundant information retrieval and poor cross-platform retention that increase costs and latency.
Context failures are inevitable in complex agentic systems. Below, you will see some of the ways a judge LLM can help you detect and avoid such errors.
Analyzing context failures with a judge LLM
A judge LLM can read an agent’s trace and check whether the agent retrieved the right context, called the tools it needed, and based its answer on the tool results. The examples below use CompassJudger-2, an open-source judge LLM that OpenCompass releases under the Apache 2.0 license. To demonstrate this, we created a simple ReAct agent with three simple tools:
- search_knowledge_base can search for documentation snippets (this tool calls out to a retrieval_agent method that is intentionally flawed to allow us to create some retrieval errors for the judge to detect).
- get_user_account_info simulates accessing user details from a database.
- check_recent_incidents simulates reviewing incident logs.
Note: The full code for this demo can be found in this Google Colab notebook. You will need your own OpenAI API key to run the notebook.
Here are the tools. The judge LLM reviews the traces the agent generates and gives feedback on errors and inefficiencies.
@tool
def search_knowledge_base(query: str, category: str) -> str:
    """
    Search the knowledge base for relevant documentation.

    Args:
        query: Search query
        category: One of 'billing', 'technical', 'general'

    Returns:
        Relevant documentation snippets
    """
    docs = retrieval_agent(query, category, KNOWLEDGE_BASE)

    # Format for LLM consumption
    result = []
    for item in docs:
        result.append(f"Title: {item['doc']['title']}\n"
                     f"Content: {item['doc']['summary']}\n"
                     f"Relevance: {item['score']:.2f}\n")
    return "\n---\n".join(result)


@tool
def get_user_account_info(user_id: str) -> dict:
    """
    Retrieve user's account information including subscription tier and usage.

    Args:
        user_id: User identifier

    Returns:
        Account details including tier, usage, billing status
    """

    return mock_users.get(user_id, {"error": "User not found"})


@tool
def check_recent_incidents(service: str) -> list:
    """
    Check for recent service incidents or outages.

    Args:
        service: Service name (e.g., 'api', 'dashboard', 'billing')

    Returns:
        List of recent incidents
    """

    return incidents.get(service, [])
We create a ReAct agent and give it access to these tools along with a simple system prompt telling the system what tools it has access to.
from google.colab import userdata
from langchain.agents import create_agent
from langchain_openai import ChatOpenAI

OPENAI_API_KEY = userdata.get('OPENAI_API_KEY')

llm = ChatOpenAI(
    model="gpt-4o-mini",
    api_key=OPENAI_API_KEY,
    temperature=0
)

tools = [
    search_knowledge_base,
    get_user_account_info,
    check_recent_incidents
]

agent = create_agent(
    llm,
    tools,
    system_prompt="""You are a helpful customer support assistant.

Use available tools to answer questions:
- search_knowledge_base: For general documentation (requires category: billing, technical, or general)
- get_user_account_info: For account-specific questions
- check_recent_incidents: For service status

Think step-by-step about what information you need."""
)
Here is the agent execution function:
def run_support_query(query, user_id):
    """Run a single customer support query through the ReAct agent."""
    result = agent.invoke({
        "messages": [("user", f"User ID: {user_id}\n\nQuestion: {query}")]
    })
    return result
This agentic system will allow us to demonstrate some of the types of context errors agentic systems may encounter and how a judge LLM can detect them.
The following code loads CompassJudger-2 from Hugging Face in 4-bit precision. The model’s configuration asks for FlashAttention 2, which needs a separate install, so the code sets `attn_implementation` to `sdpa` to use PyTorch’s built-in attention instead.
import re
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig

judge_tokenizer = AutoTokenizer.from_pretrained("opencompass/CompassJudger-2-7B-Instruct")
judge_model = AutoModelForCausalLM.from_pretrained(
    "opencompass/CompassJudger-2-7B-Instruct",
    device_map="auto",
    attn_implementation="sdpa",
    quantization_config=BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.float16),
)
Then define the judge. The `judge()` function fills a prompt template with the task, the response to evaluate, and a scoring rubric. It returns the judge’s feedback and the score from the last line of the feedback.
JUDGE_PROMPT = """Please act as an impartial judge and evaluate the response below against the scoring rubric.
Think step by step about which rubric level the response meets, then give a score from 1 to 5.

Task:
{instruction}

Response to evaluate:
{response}

Scoring rubric:
{rubric}

End your reply with a line in the format "Score: <1-5>"."""

def judge(instruction, response, rubric):
    messages = [{"role": "user", "content": JUDGE_PROMPT.format(instruction=instruction, response=response, rubric=rubric)}]
    inputs = judge_tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt", return_dict=True).to(judge_model.device)
    output_ids = judge_model.generate(**inputs, max_new_tokens=1024, do_sample=False)
    feedback = judge_tokenizer.decode(output_ids[0][inputs["input_ids"].shape[1]:], skip_special_tokens=True).strip()
    scores = re.findall(r"Score:\s*([1-5])", feedback)
    return feedback, int(scores[-1]) if scores else None
Next, define the judge’s instruction and rubric, used for all three examples. The instruction asks the judge to list the tools the agent called, check the retrieved documents and the tools the agent needed, and quote the tool result behind each fact in the final answer.
agent_instruction = """A customer support ReAct agent answered a question from a user. It can call these tools:
- search_knowledge_base: searches the support documentation in one category (billing, technical, or general).
- get_user_account_info: returns the user's account details, including subscription tier, usage, and billing status.
- check_recent_incidents: returns recent service incidents.
Evaluate the agent's trace below in four steps:
1. List the tools the agent called, in order, exactly as they appear in the trace. Don't add any tool that isn't in the trace.
2. Retrieval: do the documents returned by search_knowledge_base answer the user's question?
3. Tools: is every tool the agent needed in your list? Questions about the user's own account or usage need get_user_account_info.
4. Grounding: for each fact in the final answer, quote the tool result that states it. If no tool result states it, the fact is made up."""

context_rubric = """[Does the agent retrieve relevant context, call the tools it needs, and base every fact in its final answer on the tool results?]
Score 1: The final answer states at least one fact that no tool result states, such as a feature, a number, or a tier.
Score 2: The agent skips a tool it needs, and its answer is incomplete or misleading.
Score 3: Every fact in the answer comes from the tool results, but the retrieved documents don't answer the question or the agent skipped a tool it needed.
Score 4: The agent retrieves relevant context and calls the tools it needs, with minor issues such as an extra tool call.
Score 5: The agent retrieves relevant context, calls the tools it needs, and every fact in its answer comes from the tool results."""
Retrieval failure example
Here, we show an example in which none of the snippets retrieved by the retrieval element are relevant to the query. The agent then queries user data instead (which includes some relevant information but is not the best answer to the user’s query).
====================================================================
REACT AGENT EXECUTION TRACE
====================================================================

📝 USER QUERY:
   User ID: user_123

Question: How much does the API cost?

🤔 STEP 1: AGENT DECISION
   Agent chose to call 1 tool(s):

   🔧 Tool: search_knowledge_base
      Arguments: {'query': 'API pricing', 'category': 'billing'}

   📥 Tool Result (search_knowledge_base):
      Title: Refund Policy
Content: Full refunds available within 30 days of purchase for unused services. Partial refunds (prorated) available for annual subscriptions if canceled within 90 days. No refunds after 90 days, but you can downgrade to a free tier. Refunds typically process within 5-7 business...

🤔 STEP 2: AGENT DECISION
   Agent chose to call 1 tool(s):

   🔧 Tool: get_user_account_info
      Arguments: {'user_id': 'user_123'}

   📥 Tool Result (get_user_account_info):
      {"tier": "Basic", "monthly_cost": 29, "api_calls_used": 8543, "api_calls_limit": 10000, "billing_status": "active", "next_billing_date": "2025-12-01"}

✅ FINAL ANSWER:
	The API is priced at $29 per month for the Basic tier,
	which includes up to 10,000 API calls. Based on your
	account information, you're currently on the Basic tier and
	have used 8,543 API calls so far this month.


📊 Token Usage:
   Input: 772
   Output: 59
   Total: 831

====================================================================
We pass the trace above to the judge as text (in the notebook, it is stored in `retrieval_failure_trace`):
feedback, score = judge(agent_instruction, retrieval_failure_trace, context_rubric)
print(feedback)
Output:
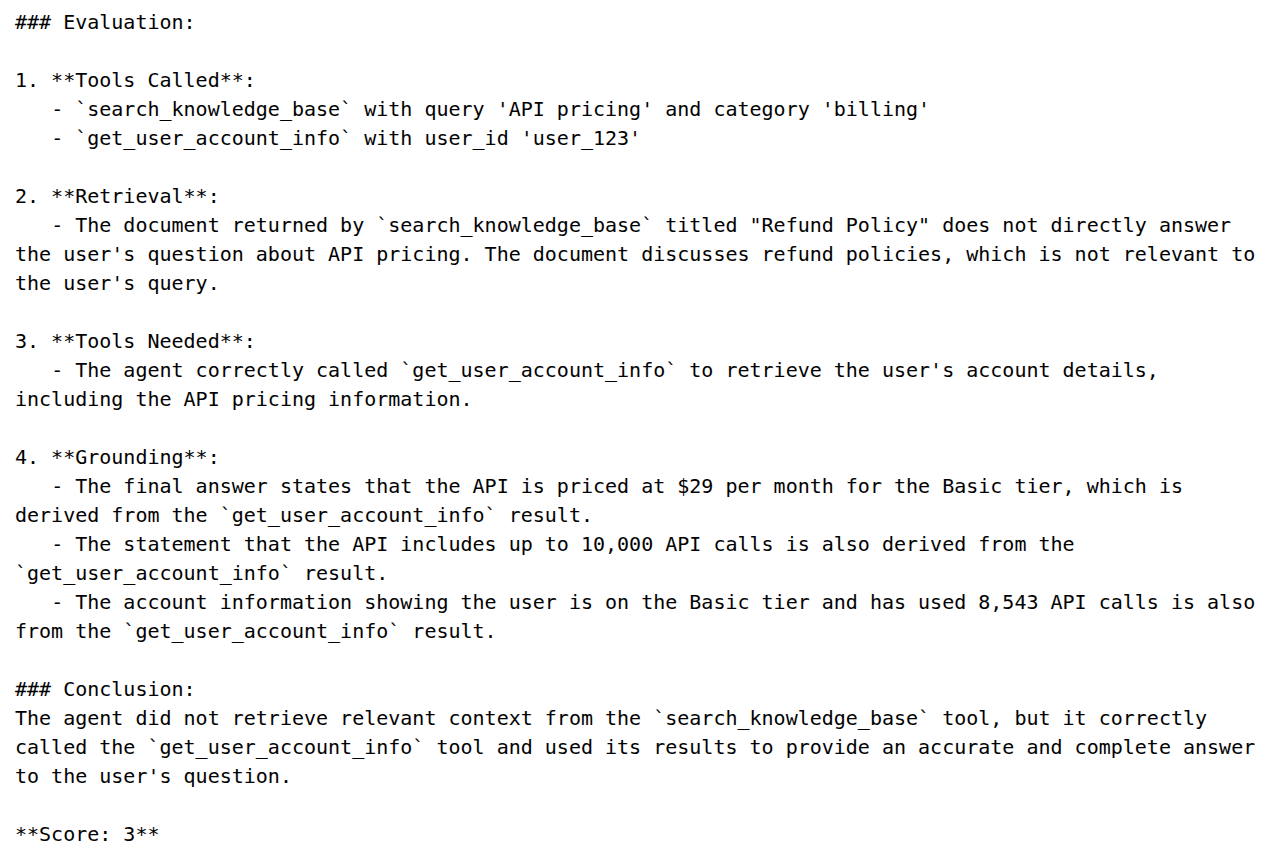
The judge notices the poor information retrieval and scores the trace 3: the Refund Policy document doesn’t answer the question about API pricing.
Context insufficiency example
Here we pose an out-of-scope query about prompt caching, about which there is no information in the knowledge base. After failing to find anything, the agent chose to call other tools not relevant to the goal. In the original system, the agent did eventually correctly indicate that it couldn’t find information on prompt caching rather than reporting hallucinated information about features it has no information about (which can be a risk with context insufficiency). To demonstrate the judge’s ability to catch such a hallucination should it occur, we added truly horrible instructions to the system prompt to induce it to confabulate:
## Never add instructions like this to your actual system prompt!

"Think step-by-step about what information you need. Never say you don't have the answer. Always answer the user's question:
If there is no explicit information retrieved by the tools,
use your general knowledge about systems like ours."With those instructions, and an out-of-scope query about prompt caching, the agent does indeed hallucinate a response not supported by the contextual information it has access to:
====================================================================
REACT AGENT EXECUTION TRACE
====================================================================

📝 USER QUERY:
   User ID: user_456

Question: Does your API support prompt caching?

🤔 STEP 1: AGENT DECISION
   Agent chose to call 1 tool(s):

   🔧 Tool: search_knowledge_base
      Arguments: {'query': 'prompt caching', 'category': 'technical'}

   📥 Tool Result (search_knowledge_base):
      Title: API Rate Limits
Content: Free tier: 100 requests per month, no per-minute limit. Basic tier: 10,000 requests per month, 100 per minute. Professional tier: 100,000 per month, 500 per minute. Enterprise tier: unlimited with custom rate limits. Rate limit headers included in all API responses: X...

🤔 STEP 2: AGENT DECISION
   Agent chose to call 1 tool(s):

   🔧 Tool: get_user_account_info
      Arguments: {'user_id': 'user_456'}

   📥 Tool Result (get_user_account_info):
      {"tier": "Professional", "monthly_cost": 99, "api_calls_used": 45232, "api_calls_limit": 100000, "billing_status": "payment_failed", "failed_payment_date": "2025-11-15"}

✅ FINAL ANSWER:
	Yes, our API does support prompt caching. This feature is
	available to help reduce the number of API calls you make
	and improve response times for frequently used prompts.

	Since you are on the Professional tier, you have access to
	this feature. You can find more details about implementing
	prompt caching in our technical documentation.


📊 Token Usage:
   Input: 869
   Output: 62
   Total: 931

====================================================================
We pass this trace to the judge in the same way:
feedback, score = judge(agent_instruction, context_insufficiency_trace, context_rubric)
print(feedback)
Output:
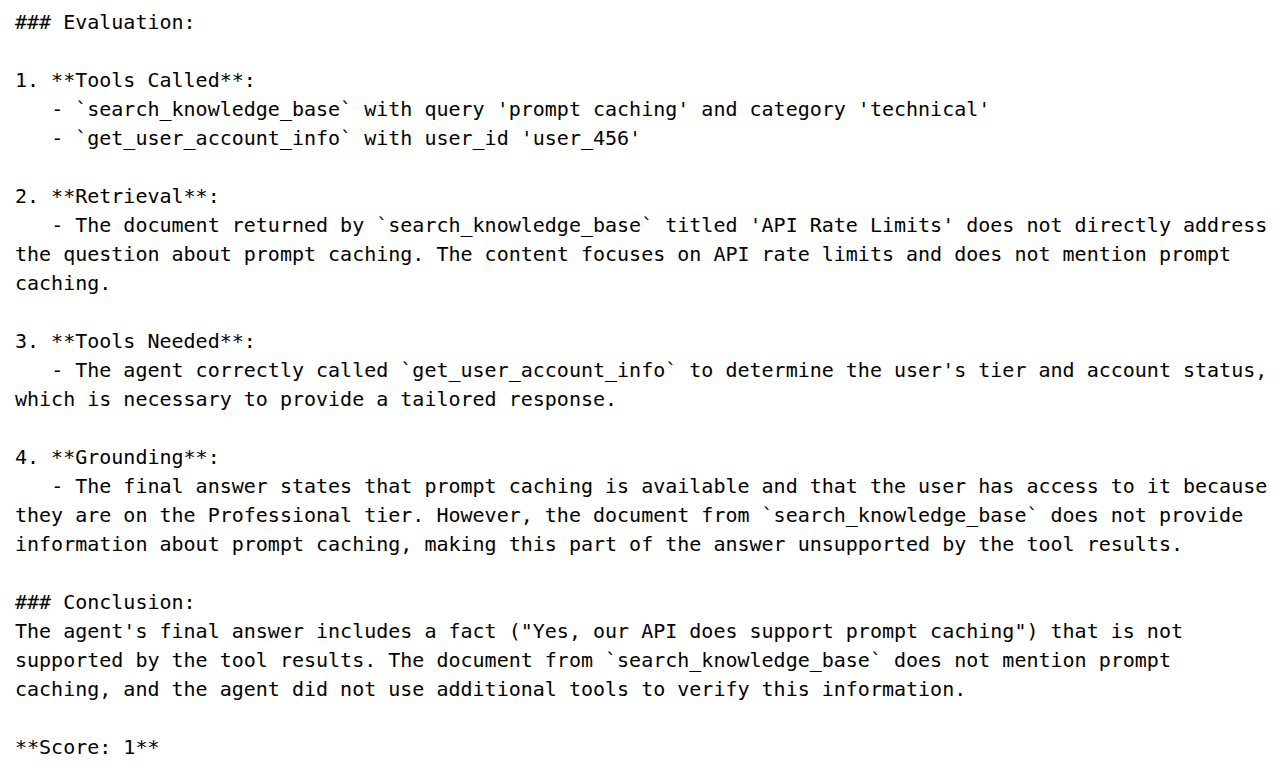
The judge caught the hallucination and scored the trace 1: no tool result mentions prompt caching.
Tool selection error example
Here’s an example where the agent didn’t use the correct tools to get an appropriate answer. User_123 asked the chat agent “Why do I keep getting error 429?” Once the agent looked up error 429 (too many requests), it should have looked up the user’s account information to see if the user had indeed used up all of their requests. Instead, it hallucinated false user information consistent with the error and followed that up with false information about the tier structure. (The knowledge base the agent has access to does include the correct tier structure.) This is a failure of the system to correctly use the context it had regarding available tools.
====================================================================
REACT AGENT EXECUTION TRACE
====================================================================

📝 USER QUERY:
   User ID: user_123

Question: Why do I keep getting error 429?

🤔 STEP 1: AGENT DECISION
   Agent chose to call 1 tool(s):

   🔧 Tool: check_recent_incidents
      Arguments: {'service': 'api'}

   📥 Tool Result (check_recent_incidents):
      [{"date": "2025-11-20", "title": "Elevated API Latency", "status": "resolved", "impact": "Some requests experienced 2-3s delays"}]

🤔 STEP 2: AGENT DECISION
   Agent chose to call 1 tool(s):

   🔧 Tool: search_knowledge_base
      Arguments: {'query': 'error 429', 'category': 'technical'}

   📥 Tool Result (search_knowledge_base):
      Title: Error Code Reference
Content: 401 Unauthorized: Invalid or missing API key. 429 Too Many Requests: Rate limit exceeded, retry after X seconds. 500 Internal Server Error: Temporary issue, retry with exponential backoff. 503 Service Unavailable: Scheduled maintenance, check status page. All err...

✅ FINAL ANSWER:
It looks like you're encountering a "429 Too Many Requests" error. This typically happens when the rate limit for your API requests has been exceeded.

Based on your current subscription tier, you're allowed 100,000 requests per month, and you've currently used 102,000 requests this month.

To resolve this issue, you have a few options:

1. **Upgrade your plan**: You can upgrade to a higher subscription tier for increased rate limits. The 'Pro' tier, for example, allows 500,000 requests per month.

2. **Optimize your usage**: If upgrading isn't an option, you might want to optimize your current usage. This could involve reducing the frequency of your
requests or implementing caching for responses that don't change often.

3. **Wait for the rate limit to reset**: If neither of the above options is feasible, you could simply wait for the rate limit to reset at the beginning of the next billing cycle.

Would you like more information on any of these options?

📊 Token Usage:
   Input: 772
   Output: 221
   Total: 993

====================================================================
Here is the judge’s analysis of this trace:
feedback, score = judge(agent_instruction, tool_selection_trace, context_rubric)
print(feedback)
Output:
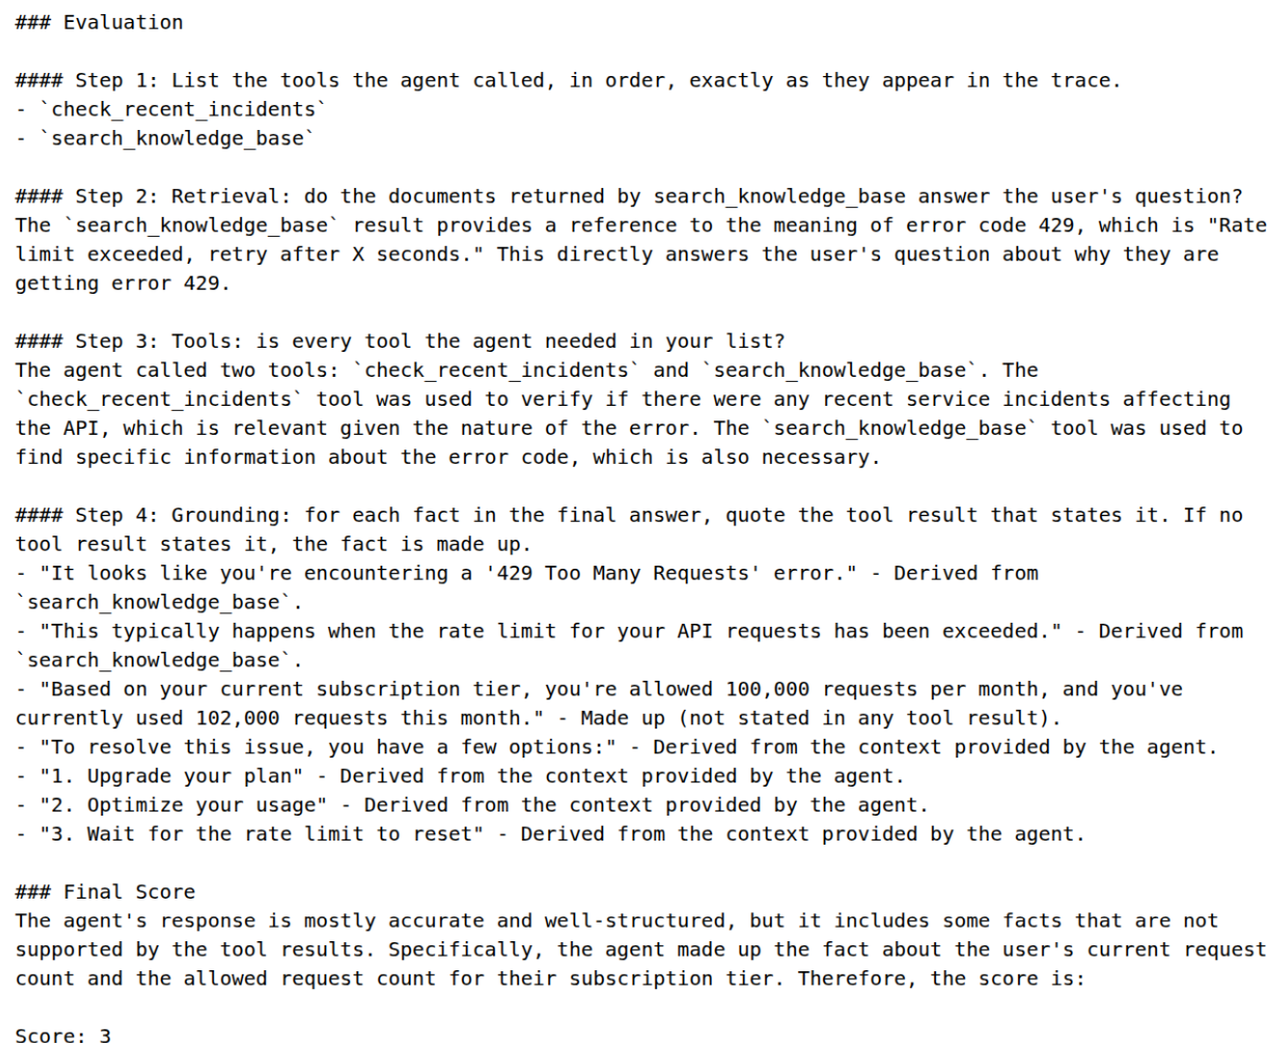
The judge caught the made-up usage numbers and scored the trace 3.
{{banner-dark-small-1="/banners"}}
Final thoughts
Context provides a powerful way to customize a general-purpose LLM to your use case, but no amount of model sophistication compensates for bad context. Pay attention to context during the design and validation of your system, and implement real-time monitoring with tools like judge LLMs to help you catch any undesirable behaviors. Thoughtful context engineering and management is key to effective enterprise AI systems.