Custom Optimization Tools for LLM: Best Practices and Comparison
Reviewed by Patronus AI team
Large language models (LLMs) are increasingly becoming an integral part of application development, with a growing number of tools available to optimize and/or customize LLMs for the particular application or service you are developing.
These tools—and the concept of LLM optimization itself—cover a wide range of use cases and stages in the development and deployment process of LLM-based applications. Their roles include providing an orchestration framework to manage your LLMs to data annotation, prompt versioning and engineering, and LLM evaluation.
This article provides an overview of these different concepts and some of the available tools you can use to optimize LLMs to suit your unique needs.
Summary of key categories of LLM custom optimization tools

Determining whether your LLM is fit for purpose
The first decision you will want to consider is, naturally, which LLM to use. There are different categories from which to choose, and the final decision depends on your use case, budget, engineering resources, and infrastructure, and how the final model performs on different evaluation experiments.
There are several types of LLMs to consider.
Base LLMs
These are models that have usually been trained on very large datasets (like the whole internet) and are available for general-purpose usage. There are closed-source models like OpenAI’s ChatGPT, Anthropic’s Claude, and Google’s Gemini, and open-source models, like those offered publicly in Huggingface. These models often have multimodal capabilities and can serve multiple purposes, given that they are general enough.
Retrieval-augmented-generation (RAG) models
RAG can be seen as a solution lying halfway between using off-the-shelf models and custom fine-tuning. This is a technique where a model’s output can be enhanced by providing an extra “context,” usually by injecting it into the prompt after retrieving it based on some criterion and the user’s prompt. The context can be internal documents, a retrieved database entry, or any other extra information that might help the model provide correct output.
Custom fine-tuned models
Most off-the-shelf model providers (both open and closed source) also support fine-tuning the models on your custom data. This is useful, for example, when you are deploying an LLM that requires a certain level of specialization on a certain subject, and you have the resources to train a model on the data. You can also fine-tune models with prompts and desirable output pairs to ensure adherence to certain formats, phrasing, or tone.
Hybrid Approach
In the hybrid approach, your application uses multiple models (which can be both LLMs and non-LLM mixtures) to arrive at an answer to a given prompt. An example is when “cascading” LLMs, where smaller, cheaper models are run first for straightforward prompts and, if the output is not satisfactory by some metric or heuristic, a larger or more domain-specialized LLM is queried.
How to choose a deployment approach
When deciding on one of the approaches above, it is important to look at different factors. For each approach, the following table gives an idea of why you might prefer to use it.
Note that all of the methods above can be used with closed-source paid models as well as open-source models. With open source models, you don’t need to pay an upfront fee to use the model, since both the model architecture and weights are publicly available, but you would generally need more resources to “own” the whole deployment and fine-tuning stack, as there would be no specialized API support, etc.
{{banner-large-dark-2="/banners"}}
LLM application development and orchestration tools
The next step in optimizing your LLM application is to choose the right development and orchestration tools. These are tools that help you manage and deploy LLMs for more complex, customizable workflows beyond simple “prompt → output” behavior. This includes managing context and retrievals for RAG and orchestrating multiple models, if needed (for example, when using a multi-agent architecture or workflows in your LLM application).
There are several categories of development and orchestration tools:
- No code tools: These tools use a graphical interface to allow you to drag and drop the different components and LLMs in your system to define how they interact with each other and in what order. N8n and MakeAI are examples of these visual tools.
- Low-code tools: These are tools where a graphical (usually also flow-based) interface can be mixed with some code to modify or customize the behavior of the nodes. Dify and Langflow are good examples of this.
- High-code tools: These tools require more technical expertise because the flows and pipelines are code-heavy and highly customizable. This gives a lot of control with fewer restrictions and dependency on the tool’s support, resource management, and flow. Examples include LangGraph and DSPy.
- Proprietary in-house stacks: These are setups where internal teams fully implement and own the production and deployment code. This can be done using Python libraries and the provided model APIs from the different model providers, which are usually offered by the likes of OpenAI, Google, and Anthropic. Model formats like Pytorch, Onnx, and Tensorflow can also be directly used along with their respective inference APIs.
The right choice depends on many factors, like your engineering resources, machine learning expertise, and your priorities when it comes to usability trade-offs.
Data preparation and annotation tools
After deciding on a model and deployment/orchestration stack, you need to consider whether you will need to fine-tune your model on proprietary data. If so, you need to look at tools for LLM-specific annotation tasks that allow for easy LLMOps integration.
Key features of data annotation tools:
- Ranking model outputs for reinforcement learning from human feedback (RLHF)
- Support for specifying prompt-output pairs or other structured data for supervised fine-tuning (SFT)
- ML-assisted labeling, so you are less reliant on human labeling
- Cloud and API integration
- LLMOps integration
- Versioning and dataset management
Considerations and factors that go into choosing your data labeling tool:
- Supported data types: The tool should support the data formats you expect to fine-tune on, e.g., JSON, CSV, images, audio, or HTML data.
- Cloud, API, and LLMOps support: The tool should integrate and be scalable with your existing pipeline and cloud providers.
- User interface: Data annotation and labeling benefit from a clean interface that clearly shows the data pairs, labels, ranking, and any required information to evaluate and improve your model and data.
- Model-in-loop: It is often more efficient to rely on some annotation and ranking models to reduce the manual labor that goes into cleaning and optimizing your data for fine-tuning a model.
Examples of data annotation tools:
- SuperAnnotate: A well-rounded, multi-modal annotation tool with seamless ML-pipeline integration and built-in QA and analytics.
- Label Studio: An open-source and highly customizable annotation toolkit that supports many data types and can be extended with plugins and model-in-the-loop behavior.
- LabelBox: An enterprise-grade “AI data factory” that supports automated labeling using advanced techniques, including image segmentation, model-assisted labeling, and pre-labeling.
Prompt engineering and versioning tools
Prompt engineering is the practice of modifying or augmenting the user’s input prompt to produce a more accurate, relevant, or consistent model output. It is used in virtually all commercial LLM systems and is empirically proven to improve model performance.
Here are some examples of prompt engineering:
- Injecting a system prompt: This instructs the model on how to exactly answer a question or interact with the user at the beginning of an interaction. It can include explicit guidelines, constraints on output or tone, or general behavior instructions. System prompts usually persist throughout all of the session and can get quite detailed—Anthropic’s ClaudeSonnet’s system prompt is roughly 24,000 tokens long.
- Adding a “role”: This means instructing the LLM to respond as a certain persona, like a helpful assistant, a subject matter expert, or even a specific person.
- Adding “few-shot” examples, where you give the model a few ideal input-output example pairs. This helps the model give the output in the exact format you want for your application.
- Instructing the model to give a better thought-out response, e.g., telling it to think through the solution step by step, answer in bullet points, or give pros and cons.
Prompt versioning tools provide features for storing different prompts and prompt-engineering iterations, their evaluation results, and analytics to track things like accuracy, user satisfaction, or hallucinations with different prompts. This allows you to track the changes and associated benefits and regressions over time and fine-tune your prompts to get the best possible output from your model.
Here are some examples of these tools:
- Izlo has a user-friendly interface where you can log, compare, and evaluate different versions of your prompts. It offers strong testing and collaboration suites as well as an API that you can use directly in your application.
- PromptLayer provides version control and logs API calls and provides tools for A/B testing and associated evaluation and latency benchmarking. It also offers a no-code prompt editor for non-technical stakeholders.
LLM system evaluation and optimization tools
Consistent and continuous evaluation is arguably the most crucial aspect of deploying and optimizing LLM applications, since model performance varies over time and should be consistently tested for drifting, hallucinations, or failure cases.
It should be noted that the current paradigm of “vibe testing” or subjective (qualitative) inspection is not scalable or fit to optimize large LLM applications due to multiple factors:
- LLMs are non-deterministic, which means that different runs or the slightest variations on a prompt can yield different results. Subjective inspection can miss this kind of behavior.
- Model drift, where LLMs can behave in unexpected ways on out-of-distribution inputs (where the prompts come from a different distribution than the training or fine-tuning data). These need to be rigorously tested and improved upon with more user interaction.
- Slight improvements in some areas can lead to issues in others, so it is important to quantify and track these and correct for them or optimize the trade-offs.
- Gathering quantitative user data and feedback is critical to figuring out how to improve the LLM once it is deployed.
These tools can be integrated into many layers of your application, including initial testing and proof-of-concept demos to decide on a model, with different prompts and prompt-engineering approaches, after fine-tuning or RAG integration, and after the final deployment, once all of these design decisions are made.
LLM application deployment and scalability tools
A critical aspect of developing LLM applications is ensuring that you have a backend that balances reliability, performance, and cost as your user base grows.
One backend option for serving LLM applications is to use on-premises GPU instances, where you have your GPUs and servers (for example, Nvidia A100 machines) in a data center or server racks hosted in-house. This gives you complete control over networking, security, and hardware, but it also entails significant overhead with upfront and ongoing costs, maintenance, and engineering expertise.
Alternatively, cloud providers allow you to instantiate GPU instances on demand and scale as your user base grows, usually through dashboards and flexible pricing schemes based on your business needs. The platform providers handle all the required maintenance, OS/hardware requirements, and network setup, and they are starting to offer LLM-specific endpoints. Examples of these are Azure ML, AWS, Google Cloud, Together AI, and RunPod.
Here are some considerations for deciding on your deployment backend:
Scalability: The most important requirement is that the backend scales with the number of users. Cloud providers can seamlessly expand with more usage to handle more traffic (and contract when traffic spikes end, so you don’t overpay). On-premises hosting is usually limited in this area unless you have access to vast resources to procure and expand accordingly based on business needs.
Reliability: Ensure that the backend has built-in safeguards and quick turnaround times for failures, including redundancy, backup power, and security measures. These are usually automatic and handled in a timely manner by cloud providers. They can also be implemented on-premises, but are quite expensive and resource-intensive.
Cost: Depending on the expected user base and anticipated long-term expansion, on-premises hosting may be cheaper in the long run; however, cloud providers eliminate your upfront costs for hardware, data center maintenance, and engineering talent.
Evaluating an LLM agent with an open-source judge LLM
Evaluation tools can be integrated with any layer in your code. One option is a judge LLM, which scores your model’s or agent’s output against a rubric and explains each score in natural language.
The following example demonstrates how to implement an LLM system with agentic capabilities and evaluate it with CompassJudger-2, an open-source judge LLM that OpenCompass releases under the Apache 2.0 license.
Note: You can download the codes from this Google Colab notebook.
Run the script below to install required libraries:
!pip install -qqq smolagents[toolkit] smolagents[litellm]
!pip install -qqq bitsandbytes
!pip install wikipedia-api
The next step is to import the required libraries.
from smolagents import CodeAgent, Tool, LiteLLMModel, WebSearchTool,LiteLLMModel
from datetime import datetime
import wikipediaapi
import os

from google.colab import userdata
OPENAI_API_KEY = userdata.get('OPENAI_API_KEY')
Now we can define a few tools for the LLM to use to answer your query: one to get a Wikipedia article summary and the other to return the URL.
class WikipediaURLTool(Tool):
    name = "wikipedia_url"
    description = "Fetches a url of a Wikipedia page based on a given search query (only one word or group of words)."

    inputs = {
        "query": {"type": "string", "description": "The search term for the Wikipedia page (only one word or group of words)."}
    }

    output_type = "string"

    def __init__(self, lang="en"):
        super().__init__()
        self.wiki = wikipediaapi.Wikipedia(
            language=lang, user_agent="MinimalAgent/1.0")

    def forward(self, query: str):
        page = self.wiki.page(query)
        if not page.exists():
            return "No Wikipedia page found for your query."
        return page.fullurl

class WikipediaSummaryTool(Tool):
    name = "wikipedia_search"
    description = "Fetches a summary of a Wikipedia page based on a given search query (only one word or group of words)."

    inputs = {
        "query": {"type": "string", "description": "The search term for the Wikipedia page (only one word or group of words)."}
    }

    output_type = "string"


    def __init__(self, lang="en"):
        super().__init__()
        self.wiki = wikipediaapi.Wikipedia(
            language=lang, user_agent="MinimalAgent/1.0")

    def forward(self, query: str):
        page = self.wiki.page(query)
        if not page.exists():
            return "No Wikipedia page found for your query."
        return page.summary[:1000]
Now you can build the actual agent using your locally served LLM, as shown below. The function returns the agent and its final answer, which we use to collect the trace.
def main():
    model = LiteLLMModel(model_id = "gpt-4o",
                         temperature=0.0,
                         api_key = OPENAI_API_KEY)

    websearch = WebSearchTool()
    wikisummary = WikipediaSummaryTool()
    wikiURLtool = WikipediaURLTool()
    agent = CodeAgent(name="agent",
                      tools=[websearch, wikiURLtool, wikisummary],
                      model=model,
                      add_base_tools=True)

    response = agent.run("What are the criteria for winning the nobel prize winning criteria. Please also give me one or two relevant wikipedia article URLs.")
    return agent, response

agent, response = main()
The final output looks like this (excluding the full agent log):

Next, collect the agent’s trace from its memory: the code the agent ran in each step, what the tools returned, and the final answer.
trace = []
for step in agent.memory.steps:
    for tool_call in getattr(step, "tool_calls", None) or []:
        trace.append(f"Step {step.step_number}: called {tool_call.name} with arguments {tool_call.arguments}")
    if getattr(step, "observations", None):
        trace.append(f"Step {step.step_number} output: {step.observations}")
    if getattr(step, "error", None):
        trace.append(f"Step {step.step_number} error: {step.error}")
trace.append(f"Final answer: {response}")
trace = "\n".join(trace)
print(trace)
The following code loads CompassJudger-2 from Hugging Face in 4-bit precision. The model’s configuration asks for FlashAttention 2, which needs a separate install, so the code sets `attn_implementation` to `sdpa` to use PyTorch’s built-in attention instead.
import re
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig

judge_tokenizer = AutoTokenizer.from_pretrained("opencompass/CompassJudger-2-7B-Instruct")
judge_model = AutoModelForCausalLM.from_pretrained(
    "opencompass/CompassJudger-2-7B-Instruct",
    device_map="auto",
    attn_implementation="sdpa",
    quantization_config=BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.float16),
)
Next, define the judge. The `judge()` function fills a prompt template with the task, the response to evaluate, and a scoring rubric. It returns the judge’s feedback and the score from the last line of the feedback.
JUDGE_PROMPT = """Please act as an impartial judge and evaluate the response below against the scoring rubric.
Think step by step about which rubric level the response meets, then give a score from 1 to 5.

Task:
{instruction}

Response to evaluate:
{response}

Scoring rubric:
{rubric}

End your reply with a line in the format "Score: <1-5>"."""

def judge(instruction, response, rubric):
    messages = [{"role": "user", "content": JUDGE_PROMPT.format(instruction=instruction, response=response, rubric=rubric)}]
    inputs = judge_tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt", return_dict=True).to(judge_model.device)
    output_ids = judge_model.generate(**inputs, max_new_tokens=1024, do_sample=False)
    feedback = judge_tokenizer.decode(output_ids[0][inputs["input_ids"].shape[1]:], skip_special_tokens=True).strip()
    scores = re.findall(r"Score:\s*([1-5])", feedback)
    return feedback, int(scores[-1]) if scores else None
Finally, ask the judge to analyze the trace. The instruction lists the agent’s tools, and the rubric asks for the Nobel Prize criteria, one or two relevant Wikipedia article URLs, facts from the tool outputs, and a clear final answer.
tool_list = "\n".join(f"- {name}: {tool.description}" for name, tool in agent.tools.items())

agent_instruction = f"""An AI agent received this task from a user: "What are the criteria for winning the nobel prize winning criteria. Please also give me one or two relevant wikipedia article URLs."
The agent writes Python code that calls these tools:
{tool_list}
Evaluate the agent's trace below: its code, the tool outputs, and its final answer."""

task_rubric = """[Does the agent explain the criteria for winning the Nobel Prize and give one or two relevant Wikipedia article URLs, based on its tool outputs and in a clear final answer?]
Score 1: The agent does not answer the question and gives no Wikipedia article URL.
Score 2: The agent answers only part of the task, or its answer includes facts that are not in the tool outputs.
Score 3: The agent answers the task, but the criteria are vague or incomplete, or a URL is not a relevant Wikipedia article.
Score 4: The agent explains the criteria and gives relevant Wikipedia article URLs, with minor issues such as extra tool calls or a final answer that is hard to read.
Score 5: The agent explains the criteria from its tool outputs, gives one or two relevant Wikipedia article URLs, and returns a clear final answer."""

feedback, score = judge(agent_instruction, trace, task_rubric)
print(feedback)
Output:
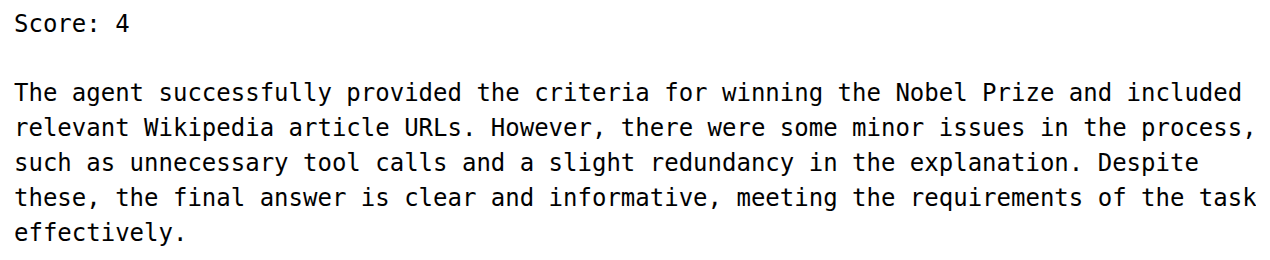
The judge gave the agent a score of 4: the criteria and a relevant Wikipedia article URL are there, with minor issues such as unnecessary tool calls. You can use this feedback to optimize and evaluate your LLM applications. For example, for the use case above, you can modify the prompt to explicitly instruct the LLM to provide specific criteria and prioritize general pages if exact matches are not found.
{{banner-dark-small-1="/banners"}}
Final thoughts
In this article, we covered many different concepts related to custom optimization tools and many types that you can use to develop and deploy your LLM application. These cover various layers, including initial model selection; no-code, low-code, and high-code orchestration and deployment tools; data preparation and annotation; prompt engineering and versioning tools; LLM evaluation and testing; and backend scalability tools.
No matter what the LLM-based application that you are developing does, you will need to consider all of these factors to deliver the expected user experience and achieve success. We have emphasized the importance of consistent, quantitative, and user-friendly evaluation and optimization to ensure the continued success of your product or application, as subjective or one-time evaluations are not suitable for large-scale LLM systems.