AI Agent Routing: Tutorial & Best Practices
Reviewed by Patronus AI team
Modern agent-based applications involve multiple agents that perform different tasks and collaborate to perform desired actions. In a typical workflow, data is continuously exchanged between different agents to achieve a common goal. Selecting the right agent for handling input at any given time is imperative to building robust and scalable AI agent-based applications.
This article examines AI agent routing, common patterns, and methods for evaluating AI agent routing decisions. It also includes a hands-on example of implementing different agent routing techniques and explores different implementation platforms.
Summary of key AI agent routing concepts
What is AI agent routing?
AI agent routing refers to selecting which specialized agent or set of agents should handle a piece of input at any step in a multi-agent workflow. It ensures coherence between multiple agents and introduces a separation of concerns between task performance and collaboration. The routing agent handles collaboration, while other agents can focus on their individual tasks.
In simple terms, an AI router agent determines which agent is best suited to handle the input at a specific stage of an LLM pipeline.
Throughout this article, the term “AI agent routing” refers to both the logic that determines the next agent and the surrounding infrastructure, such as prompts, models, and rules.
Importance of agent routing
A modern LLM application can have dozens of agents, such as retrievers, planners, tool callers, etc, specialized for specific tasks. A misclassified input can trickle down through multiple incorrect agents, compounding hallucinations and incorrect responses. Inconsistent behavior causes users to lose confidence in the system. Incorrect agents also consume additional input and output tokens, thereby increasing the overall cost.
In contrast, correct routing preserves conversational state. The agent that handles the previous step often holds crucial memory. A correct routing decision continues the chain and does not force the system to re-infer context, decreasing the chances of hallucinations.
With explicit routing traces, you can also identify whether the bad answer was an agent-level fault or simply a misclassification at the router level.
Agent routing approaches
Agent routing approaches have evolved lately, transitioning from rule-based to machine learning and LLM-based methods.
Rule-based
Rule-based agent routing approaches involve hard-coded rules, such as keyword spotting or pattern matching, to direct user queries to the appropriate code path. For instance, a rule might route queries containing “credit card” to the credit card assistant. Rule-based approaches are straightforward to implement but lack flexibility.
Machine learning based
Machine learning approaches involve training machine learning models on routing datasets and using the trained model in production to route user queries to the concerned models. Dialogue act and intent classification datasets are examples of routing datasets. A user's intent, such as a question, statement, or greeting, is routed to a corresponding agent. This approach is more flexible compared to rule-based routing, but it may require a large training dataset to achieve good results.
LLM-based approaches
Large language models (LLM) based approaches are the state-of-the-art for agent routing. These approaches rely on an LLM's pre-trained knowledge, coupled with prompt engineering techniques, to route a user query to the relevant agent. Routing agents can be further improved by fine-tuning LLMs on routing data or by utilizing retrieval augmented generation (RAG) techniques. Almost all modern AI applications rely on LLM-based agent routing.
AI agent routing patterns
Depending on the application you want to develop, your multi-agent workflows can implement various agent routing patterns.
Single and multi-agent routing
Single-agent routing is the simplest scenario for AI agent routing. A router agent routes a user's input or response from an upstream agent to one and only one predefined agent. The router agent typically consists of an LLM and a prompt, which specifies it to redirect the query to the concerned agent.
The following figure demonstrates a single-agent routing workflow. A single solid line shows that the user input is routed to only one agent.

Multi-agent routing can route the input query to multiple agents. In the following figure, two solid lines indicate that the router routes the input to both CARD ASSISTANT and LOGIN_ASSISTANT simultaneously.

Multi-agent workflows can have layers of agents stacked in a hierarchy.

Example
Consider a banking application with three agents:
- Credit card assistant
- Login assistant
- Default assistant.
In single-agent routing, the router agent processes the user's input and selects the most appropriate assistant to respond to it.
In multi-agent routing, if a user reports, “I have a credit card issue and I cannot log in to my account,” the multi-agent router simultaneously routes the query to both the credit card assistant and the login assistant. Another assistant merges the responses from both assistants and sends the merged response to the user.
In hierarchical routing, the level-1 router routes a user query to one of the credit card, login, or default assistants. Additionally, there are two different agents for users logging in for the first time and for existing users. A level-2 router selects the first login assistant or the existing login assistant.
Event-driven agent routing
Agent routing is not triggered solely by input text queries. Application events, such as “user submitted form,” “payment succeeded,” and “message received,” can also trigger agent workflows.
For example, a “user_profile_complete” event can trigger a “Welcome Agent” that offers onboarding guidance to the new user.
Similarly, you can return the confidence level of an agent response and, based on that, trigger the “agent_low_confidence” workflow, which reroutes the query to a human review agent for human-in-the-loop tasks.
However, the routing patterns remain largely the same; an event may trigger a single agent, multiple agents in parallel, or multiple agents stacked in a hierarchy.
AI agent routing platforms
AI agent routing is a crucial component of an AI application. Hence, almost all the major pro-code, low-code, and no-code AI platforms support implementing AI agent routing.
LangChain/LangGraph
At the time of writing, LangChain is the most widely used orchestration platform for developing AI agents. LangChain offers flexible chaining of LLMs, tools, and memory to create customizable, modular agents with routing capability. LangGraph, a library from LangChain, implements acyclic graphs, which simplify the implementation of complex hierarchical routing scenarios.
CrewAI
CrewAI supports multi-agent routing via low-code and pro-code tools. It allows you to implement routing scenarios using the visual builder as well as via a Python SDK. It supports integration with all major platforms, including OpenAI, Anthropic, and AWS, among others.
SmolAgents
SmolAgents is a lightweight agent code orchestration framework developed by HuggingFace, the world's leading open-source library for implementing AI applications. SmolAgents abstracts the complexities of implementing advanced AI agents in a few lines of code.
Langflow
Langflow offers a visual LLM workflow builder tool, where you can drag and drop AI application components, such as agents, routing paths, tools, and data sources, and specify the relationships between them to develop a fully functional LLM application.
n8n
n8n supports AI agent integration and workflow automation using a low-code interface. It provides a visual workflow editor, integration with LangChain, and supports no-code, low-code, and hybrid workflow implementation approaches.
{{banner-large-dark-2="/banners"}}
LangGraph examples for AI agent routing
To give you a taste of how agent routing works, let’s see a couple of code examples implemented in the LangGraph framework.
Single-agent routing example
Run the following script to install the Python LangGraph and OpenAI libraries. You can run this code in Google Colab, so you don't need to install any additional libraries.
!pip install -qU langgraph
!pip install -qU langchain-openai
The following script imports the required libraries into your Python application.
from typing import Annotated
from typing_extensions import TypedDict,  Literal
from pydantic import BaseModel, Field
from langgraph.graph import StateGraph, START, END

from langchain_openai import ChatOpenAI
from langchain_core.messages import HumanMessage, SystemMessage
from langchain_core.output_parsers import PydanticOutputParser

from google.colab import userdata
OPENAI_API_KEY = userdata.get('OPENAI_API_KEY')
In LangGraph, you can specify the graph state that contains information that can be shared between multiple nodes in the graph. The nodes contain agents that can access the shared information.
The following code defines the LLM for your agents and the graph state. The graph contains three values:
- Query that stores the user input
- Category that stores the query category
- Response which stores the application response.
In addition, the ‘Categories’ class has a literal type ‘category’ attribute that stores the three category values. The routing agent selects one of these three values depending on the user input.
llm = ChatOpenAI(model="gpt-4o",
                 api_key = OPENAI_API_KEY)

class State(TypedDict):
    query: str
    category: str
    response: str

class Categories(BaseModel):
    category:Literal["LOGIN_ASSISTANT", "CARD_ASSISTANT", "DEFAULT_ASSISTANT"] = Field(description="The category of the query")
The next code block defines the routing agent that routes the user query to one of the predefined categories. The ‘llm.with_structured_output(Categories)’ function ensures the LLM returns one of the three predefined categories. You can also see the system prompt, which instructs the routing agent about the category selection.
The response from the routing agent is stored in the ‘category’ attribute of the graph state.
def router(state: State):

    system_prompt = """
    You are a classifier that analyzes user queries and assigns them to one of the following categories:

    - LOGIN_ASSISTANT: The query is about login issues, account access, password reset, etc.
    - CARD_ASSISTANT: The query is about credit/debit cards, transactions, card issues, etc.
    - DEFAULT_ASSISTANT: Anything else that does not fit into the above two categories.

    Return only one of the above category names in the response.
    """

    router = llm.with_structured_output(Categories)

    response = router.invoke([
        SystemMessage(content=system_prompt),
        HumanMessage(content=state["query"])
    ])

    print(response)

    return {"category":response.category}
The next code block defines a function that returns the value of the ‘attribute’ from the graph state while also defining a conditional edge in the graph. It also includes three assistant definitions that currently return a dummy value. In real-life scenarios, the assistants also contain LLMs and generate an appropriate response in accordance with organizational protocols.
def route_to_assistant(state: State):
  return state["category"]


def login_assistant(state: State):
  return {"response":"Hello from login assistant"}

def card_assistant(state: State):
  return {"response":"Hello from card assistant"}

def default_assistant(state: State):
  return {"response":"Hello from default assistant"}
The final code block adds the assistants to the graph nodes. The entry point to the ‘router’ node is also set.
It also contains a conditional edge that specifies that after the ‘router’ node, the ‘route_to_assistant’ method must be called, and depending on its output, the graph flow is redirected to either of the three assistants. This is the core component of a router agent in LangGraph.
graph_builder = StateGraph(State)

graph_builder.add_node("router", router)
graph_builder.add_node("login_assistant", login_assistant)
graph_builder.add_node("card_assistant", card_assistant)
graph_builder.add_node("default_assistant", default_assistant)

graph_builder.set_entry_point("router")
graph_builder.add_conditional_edges(
    "router",
    route_to_assistant,
    {
        "LOGIN_ASSISTANT": "login_assistant",
        "CARD_ASSISTANT": "card_assistant",
        "DEFAULT_ASSISTANT": "default_assistant",
    }
)
graph_builder.add_edge("login_assistant", END)
graph_builder.add_edge("card_assistant", END)
graph_builder.add_edge("default_assistant", END)
graph = graph_builder.compile()
You can visualize the graph using the following script.
from IPython.display import Image, display
try:
    display(Image(graph.get_graph().draw_mermaid_png()))
except Exception:
    pass

Finally, you can invoke the graph using the following script.
input = {"query": "I am having login issues with my account."}
output = graph.invoke(input)
output
The output is as follows. It shows the response from each node. The router node sets the ‘category’ attribute to ‘LOGIN_ASSISTANT’; therefore, the routing function sends the request to the ‘login assistant’, which returns a hard-coded response.

In real-world applications, partial or complete conversation histories are sent along with the user's input to an agent.
Multi-agent routing
Multi-agent routing in LangGraph returns multiple category values from a routing agent but otherwise works similarly to single-agent routing.
Here is an example.
from typing_extensions import List
import operator
class State(TypedDict):
    query: str
    categories: List[str]
    response: Annotated[list, operator.add]

class Categories(BaseModel):
    categories: List[Literal["LOGIN_ASSISTANT", "CARD_ASSISTANT", "DEFAULT_ASSISTANT"]] = Field(
        description="All applicable categories for the query"
    )
You can see that the model state now contains a category list instead of a string value. Similarly, the routing prompt tells the routing agent to return all applicable categories.
def router(state: State):
    system_prompt = """
    You are a classifier that analyzes user queries and assigns all applicable categories from the following list:

    - LOGIN_ASSISTANT: The query is about login issues, account access, password reset, etc.
    - CARD_ASSISTANT: The query is about credit/debit cards, transactions, card issues, etc.
    - DEFAULT_ASSISTANT: Anything else that does not fit into the above two categories.

    Return all relevant categories in the following JSON format:
    { "categories": ["CATEGORY_1", "CATEGORY_2"] }
    Only include relevant ones.
    """

    router_chain = llm.with_structured_output(Categories)

    response = router_chain.invoke([
        SystemMessage(content=system_prompt),
        HumanMessage(content=state["query"])
    ])

    print(response)
    return {"categories": response.categories}


def route_to_assistant(state: State) -> list[str]:
    return state["categories"]
The rest of the logic remains the same. You define three assistant nodes, then compile the graph.
def login_assistant(state: State):
    return {"response": ["Hello from login assistant"]}

def card_assistant(state: State):
    return {"response": ["Hello from card assistant"]}

def default_assistant(state: State):
    return {"response": ["Hello from default assistant"]}

graph_builder = StateGraph(State)

graph_builder.add_node("router", router)
graph_builder.add_node("LOGIN_ASSISTANT", login_assistant)
graph_builder.add_node("CARD_ASSISTANT", card_assistant)
graph_builder.add_node("DEFAULT_ASSISTANT", default_assistant)

graph_builder.set_entry_point("router")

graph_builder.add_conditional_edges(
    "router",
    route_to_assistant,
    ["LOGIN_ASSISTANT", "CARD_ASSISTANT", "DEFAULT_ASSISTANT"]
)

graph_builder.add_edge("LOGIN_ASSISTANT", END)
graph_builder.add_edge("CARD_ASSISTANT", END)
graph_builder.add_edge("DEFAULT_ASSISTANT", END)

# Compile the graph
graph = graph_builder.compile()
display(Image(graph.get_graph().draw_mermaid_png()))

The graph may resemble the single-agent routing graph; however, in this case, a query can be routed to multiple agents simultaneously, as illustrated in the following example.
input = {"query": "I am having login issues with my account. I want to access my card settings"}
output = graph.invoke(input)
output

The above output shows that the routing agent routed the input query to both ‘LOGIN_ASSISTANT’ and ‘CARD_ASSISTANT’.
Hierarchical routing
For a hierarchical routing example, we add another level of routing that determines whether the user is logging in for the first time or is an existing user. In the graph state below, we add an attribute for the ‘login_type’, which stores the result from the login type router.
The code block below also defines the ‘LoginType’ class, which contains the ‘login_type’ literal that stores either the ‘FIRST_LOGIN’ or ‘EXISTING_LOGIN’ string, depending on the login assistant router output.
class State(TypedDict):
    query: str
    categories: str
    login_type: str
    response: str

class Categories(BaseModel):
    categories: Literal["LOGIN_ASSISTANT", "CARD_ASSISTANT", "DEFAULT_ASSISTANT"] = Field(
        description="All applicable categories for the query"
    )

class LoginType(BaseModel):
    login_type: Literal["FIRST_LOGIN", "EXISTING_LOGIN"] = Field(
        description="All applicable categories for the query"
    )
The next code block defines the first-level router as before, which determines whether the input should be redirected to the credit card, login, or default assistant.
def router(state: State):
    system_prompt = """
    You are a classifier that analyzes user queries and assigns all applicable categories from the following list:

    - LOGIN_ASSISTANT: The query is about login issues, account access, password reset, etc.
    - CARD_ASSISTANT: The query is about credit/debit cards, transactions, card issues, etc.
    - DEFAULT_ASSISTANT: Anything else that does not fit into the above two categories.

    Return all relevant categories in the following JSON format:
    { "categories": ["CATEGORY_1", "CATEGORY_2"] }
    Only include relevant ones.
    """

    router_chain = llm.with_structured_output(Categories)

    response = router_chain.invoke([
        SystemMessage(content=system_prompt),
        HumanMessage(content=state["query"])
    ])

    print(response)
    return {"categories": response.categories}


def route_to_assistant(state: State) -> list[str]:
    return state["categories"]
In this case, the login assistant does not return a response. Rather, it acts as a router and determines whether this is a first-time login or an existing user login. It stores the result in the ‘login_type’ attribute of the state graph.
def login_assistant(state: State):
    system_prompt = """
    You are a classifier that analyzes user queries and tells whether the user is logging in for the first time.

    FIRST_LOGIN: The user is logging in for the first time.
    EXISTING_LOGIN: The user is logging in for the second time or more.

    Return only one of the above category names in the response.
    """

    router_chain = llm.with_structured_output(LoginType)

    response = router_chain.invoke([
        SystemMessage(content=system_prompt),
        HumanMessage(content=state["query"])
    ])

    print(response)
    return {"login_type": response.login_type}


def route_to_login_assistant(state: State) -> list[str]:
    return state['login_type']
The final code block defines the four assistants that generate responses to user queries. Notice here the ‘first_login_assistant’ and ‘existing_login_assistant.’ One of them will be selected based on the output of the ‘login_assistant’.
def first_login_assistant(state: State):
    return {"response": ["Hello from first login assistant"]}

def existing_login_assistant(state: State):
    return {"response": ["Hello from existing login assistant"]}

def card_assistant(state: State):
    return {"response": ["Hello from card assistant"]}

def default_assistant(state: State):
    return {"response": ["Hello from default assistant"]}
You can now add the graph routers and assistants, define conditional edges, and compile the graph.
graph_builder = StateGraph(State)

graph_builder.add_node("router", router)
graph_builder.add_node("login_assistant", login_assistant)
graph_builder.add_node("first_login_assistant", first_login_assistant)
graph_builder.add_node("existing_login_assistant", existing_login_assistant)
graph_builder.add_node("card_assistant", card_assistant)
graph_builder.add_node("default_assistant", default_assistant)

graph_builder.set_entry_point("router")

graph_builder.add_conditional_edges(
    "router",
    route_to_assistant,
    {
        "LOGIN_ASSISTANT": "login_assistant",
        "CARD_ASSISTANT": "card_assistant",
        "DEFAULT_ASSISTANT": "default_assistant",
    }
)


graph_builder.add_conditional_edges(
    "login_assistant",
     route_to_login_assistant,
    {
        "FIRST_LOGIN": "first_login_assistant",
        "EXISTING_LOGIN": "existing_login_assistant",
    }
)

graph_builder.add_edge("login_assistant", END)
graph_builder.add_edge("card_assistant", END)
graph_builder.add_edge("default_assistant", END)

graph = graph_builder.compile()
display(Image(graph.get_graph().draw_mermaid_png()))
The above script returns the following output.

Test the graph as follows.
input = {"query": "Hello I have issues logging into my account for the first time"}
output = graph.invoke(input)
output
The output shows that the top-level router selected the `LOGIN_ASSISTANT` category, and then the second-level router (login_assistant) selected the `FIRST_LOGIN` assistant.

Evaluating agent routing
Evaluating AI agent routing can be considered a classical case of a multi-class or multi-label classification problem. Likewise, classification metrics such as accuracy, precision, recall, and ROC curves work well for evaluation.
To evaluate AI agent routing capabilities, you ideally curate a custom dataset that encompasses all types of potential user queries. You can then train a model on the dataset and measure its performance on the test set.
Evaluating agent routing in an LLM application pipeline can be trickier, as multiple interacting components are involved in finalizing a routing decision. In such cases, visually tracing the flow of calls from the application input to the routing agent output can provide insights into the root cause of a particular decision.
While these evaluation techniques indicate how well a model performs, they cannot explain why a model performs a particular way or what causes a routing agent to route the input query to the wrong agent. This is where Judge LLMs come to play.
Judge LLMs can evaluate a model’s response, such as routing output, and explain the reasoning behind the agent’s decision. This is crucial when you want to see why a model, particularly a routing agent, routes a query to a particular path.
AI agent routing evaluation example with Judge LLMs
Examples of Judge LLMs include CompassJudger-2, an open-source model that scores an output against criteria you define and explains its score. Published research on Judge LLMs also includes GLIDER, a small model trained for the same task, and Lynx, a model trained to check whether a response is faithful to its context.
Judge LLMs help evaluate a point-in-time routing output. However, they lack contextual understanding of the events in an LLM application pipeline that led to the routing agent’s decision. To give the judge that context, you can pass it the entire routing trace, which lists every node that handled the query and the decision each node made.
Here’s how you can use CompassJudger-2 to evaluate the hierarchical routing scenario discussed in the previous section.
You can find the complete code for this article in this Google Colab notebook.
Colab already includes PyTorch and Transformers, so you only need to install bitsandbytes, which loads the model in 4-bit precision.
!pip install -qU bitsandbytesThe following code imports the libraries and loads CompassJudger-2 from Hugging Face in 4-bit precision. The model’s configuration asks for FlashAttention 2, which isn’t installed in Colab, so the code sets ‘attn_implementation’ to ‘sdpa’ to use PyTorch’s built-in attention instead.
import re
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig

judge_tokenizer = AutoTokenizer.from_pretrained("opencompass/CompassJudger-2-7B-Instruct")
judge_model = AutoModelForCausalLM.from_pretrained(
    "opencompass/CompassJudger-2-7B-Instruct",
    device_map="auto",
    attn_implementation="sdpa",
    quantization_config=BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.float16),
)
Next, define the judge. The ‘judge()’ function fills a prompt template with the task, the response to evaluate, and a scoring rubric. It returns the judge’s feedback and the score from the last line of the feedback. The routing instruction lists the available agents, so the judge knows which agent should handle which request. The rubric describes what each score from 1 to 5 means.
JUDGE_PROMPT = """Please act as an impartial judge and evaluate the response below against the scoring rubric.
Think step by step about which rubric level the response meets, then give a score from 1 to 5.

Task:
{instruction}

Response to evaluate:
{response}

Scoring rubric:
{rubric}

End your reply with a line in the format "Score: <1-5>"."""

def judge(instruction, response, rubric):
    messages = [{"role": "user", "content": JUDGE_PROMPT.format(instruction=instruction, response=response, rubric=rubric)}]
    inputs = judge_tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt", return_dict=True).to(judge_model.device)
    output_ids = judge_model.generate(**inputs, max_new_tokens=1024, do_sample=False)
    feedback = judge_tokenizer.decode(output_ids[0][inputs["input_ids"].shape[1]:], skip_special_tokens=True).strip()
    scores = re.findall(r"Score:\s*([1-5])", feedback)
    return feedback, int(scores[-1]) if scores else None

routing_instruction = """Route the following banking query to the agents that can handle it.

Available agents:
- login_assistant: routes login issues to first_login_assistant (first-time logins) or existing_login_assistant (returning users).
- card_assistant: handles credit and debit cards, transactions, and card issues.
- default_assistant: handles anything else.

Query: {query}"""

routing_rubric = """[Does the route send every request in the user's query to an agent that can handle it?]
Score 1: The route sends the query to an agent that cannot handle any of its requests.
Score 2: The route handles a small part of the query and misses the main request.
Score 3: The route handles one request in the query but ignores another request.
Score 4: The route handles every request, but one agent in the path is not the best fit.
Score 5: The route sends every request in the query to the agent best suited to handle it."""
The ‘run_graph()’ function below streams the graph’s updates to record the decision of each node. It sends this routing trace to the judge and prints the trace with the judge’s feedback.
def run_graph(user_query: str):
    trace = []
    for step in graph.stream({"query": user_query}, stream_mode="updates"):
        trace.extend(f"{node}: {output}" for node, output in step.items())
    trace = "\n".join(trace)

    feedback, score = judge(routing_instruction.format(query=user_query), trace, routing_rubric)
    print(f"Trace:\n{trace}\n\nJudge feedback:\n{feedback}")


query = "Hello I have issues logging into my account. I was able to log into it before"
run_graph(query)
Running the code prints the routing trace and the judge’s feedback:
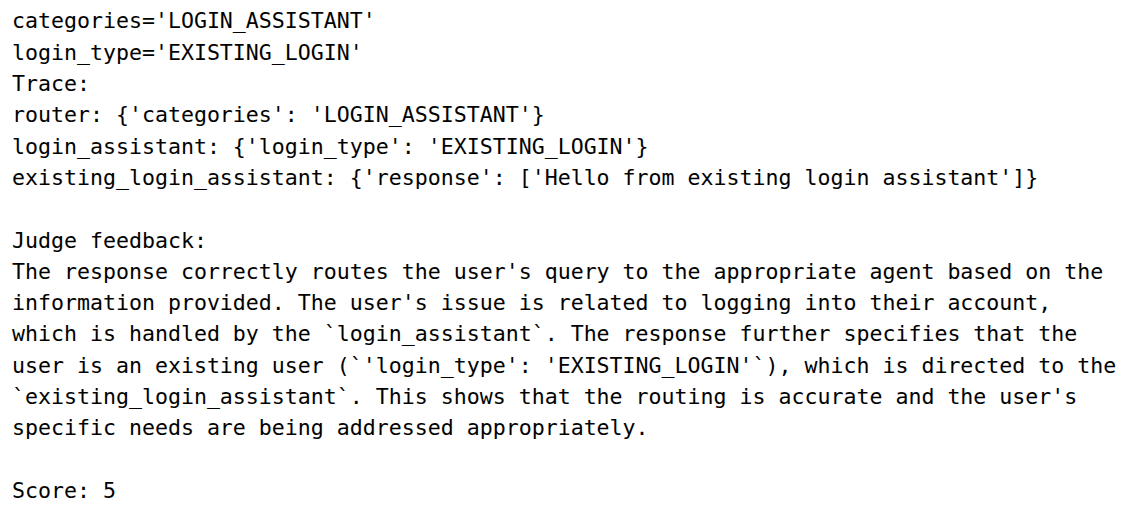
The trace in the output shows that:
- The graph execution begins at the ‘router’ node.
- It routes the query to the ‘login_assistant’ through the ‘route_to_assistant’ function.
- The ‘login_assistant’ node routes the query to the ‘existing_login_assistant’ via the ‘route_to_login_assistant’ function.
The judge confirms that both routing steps sent the query to the right agent, and it gives the route a score of 5.
Here is another query that you can evaluate with the same function.
query = "Hello I have issues logging into my account. Can you please refund my money."
run_graph(query)
Running the code prints the following output:
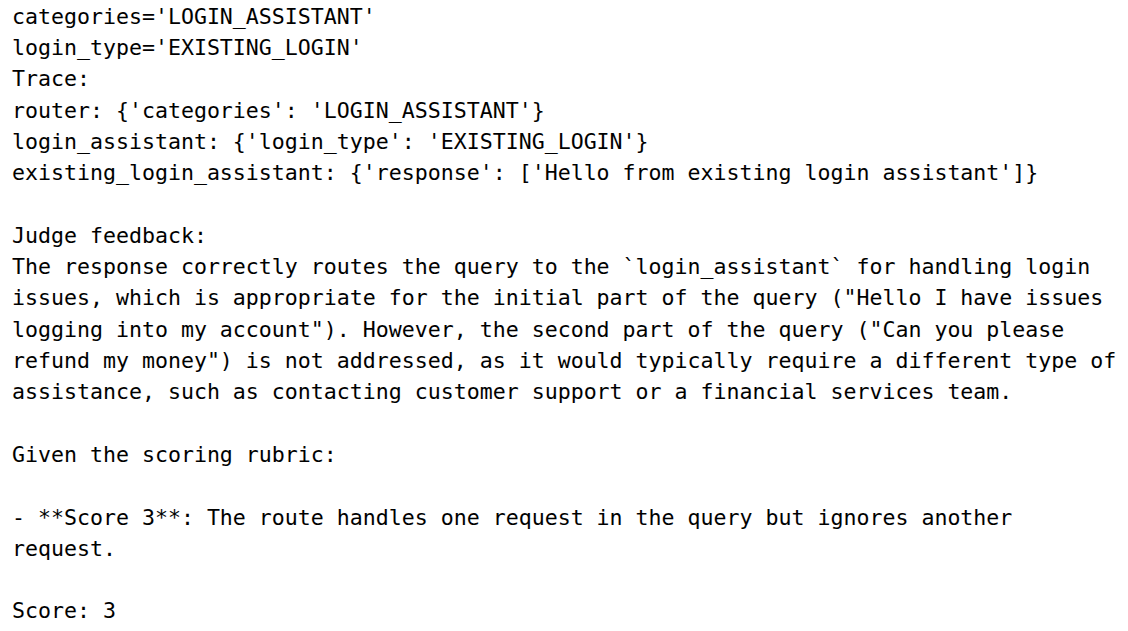
The judge gives this route a score of 3. Its feedback explains that the route handles the login issue but ignores the refund request. The hierarchical router selects a single category for each query, so one of the two requests is lost. To handle queries with more than one request, you can let the router select several categories, as in the multi-agent routing example earlier in this article.
Challenges and best practices for AI agent routing
The following are some challenges and best practices for implementing AI agent routing:
Define clear agent roles
Ambiguity in agent selection is a primary challenge in agent routing. Assign agents specific roles and responsibilities to prevent overlap and confusion. Each agent must operate within its domain, and the distinctions must be specified in the routing prompt. Additionally, add some examples of routing scenarios in the prompt.
Start simple and scale gradually
Routing errors occur more frequently with a large number of agents stacked in a hierarchical pattern. Begin by building simple logic to handle basic routing scenarios and add complexity as your application grows.
Maintain context across interactions
Preserving context is crucial for making accurate routing decisions, particularly in multi-turn conversations. Ensure that the agents have access to the conversation history and context to provide coherent and personalized responses.
Implement error handling and fallback mechanisms
Users can be unpredictable in what they ask agents. Often, none of the existing agents can correctly respond to user input. In such a case, it is essential to implement logic to handle unexpected inputs gracefully. Implement fallback strategies such as a default assistant or redirection to a human agent.
Implement API Security and Permission
Implement API permissions to ensure that agents can only access authorized API functions. For example, an Agent X responsible for assisting users with credit card issues must not access the API and tools reserved for Agent Y dealing with login issues, and vice versa.
Evaluate routing performance in production
Concept drift is another major challenge in agent routing. Concept drift occurs when a trained model consistently encounters scenarios not mentioned in the training data or during training. Consistently evaluate model routing performance to identify concept drift and areas for improvement.
Train and optimize the routing model
Routing agent evaluation can help you identify the problem areas and inaccurate routing decisions. Consistently optimize and train your routing models to reduce routing errors.
{{banner-dark-small-1="/banners"}}
Last thoughts
AI agent routing is a crucial component of AI applications that involve multiple agents. An incorrect routing decision can lead to a chain of errors, resulting in inconsistent system behaviour that loses user trust.
Robust AI agent routing evaluation mechanisms ensure that your application is reliable, trustworthy, and easy to debug. For example, an open-source Judge LLM such as CompassJudger-2 can score each routing decision against a rubric and explain which part of a user’s request a route misses.